Why
Why let an agent do more work before you look again? It can give you time to explore alternatives or attempt something you wouldn’t have built yourself. It also leaves you with more work to assess. Whether that trade-off pays off depends on the task, the agent’s working conditions, and how well you can judge the result.
Faster implementation changes where you spend time
When implementation gets faster, the decisions around it can take a larger share of the team’s time:
- At the front: what is worth building, who it is for, what good would look like.
- At the back: whether what came back is any good, and what production teaches you once it ships.
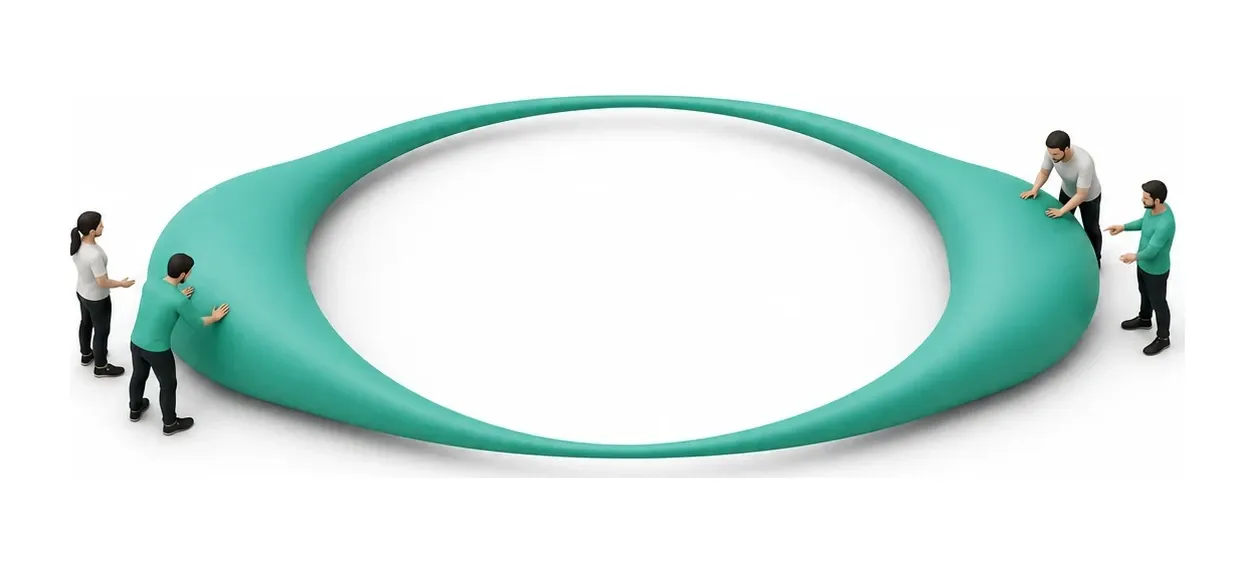
When implementation speeds up, review or product decisions can become the limiting step. More work can accumulate while waiting for those decisions. Eliyahu Goldratt’s Theory of Constraints provides a way to examine such constraints. For your team, how long does work wait for a decision about what to build or whether to accept it?
You may have experienced this: an agent hands you a feature in minutes, and you spend an hour working out whether it does what you wanted. Include that hour when assessing the benefit of delegation.
Agentic engineering is machine learning
François Chollet describes agentic engineering as a form of machine learning in a post on X from May 2026. The engineer defines the goal, constraints, and Search spaceThe set of candidate solutions an agent can explore for a task.Several implementations can satisfy the same requirement. Constraints help narrow the choice. of possible solutions. The agent generates code and uses evaluation results to revise it. In this view, you assess the result as a Blackbox artifactA result assessed through its observable behavior without inspecting its internal implementation.Trying the dashboard with representative cases before examining its code.: examine what it does, including on cases beyond those used to develop it. That ability to work on unfamiliar cases is GeneralizationThe ability to work on cases beyond those used to develop or adjust a solution.Does the fix also handle inputs beyond those described in the ticket?.
This view puts attention on how the task is framed and evaluated. A specification can state known requirements and leave room to explore unresolved choices. Grading explains how it develops with the work. The Evaluation functionA method for scoring a proposed result against defined criteria.A test suite or checklist used to assess successive attempts., the method used to score a proposed result, needs its own assessment: a passing score is useful only when the criteria reflect what the team needs.
I find the constant focus on productivity boring. I want to know whether we’re building better products and attempting things we previously couldn’t. Counts of pull requests tell us how much work was submitted. We also need to know whether it was useful, what it cost to review, and how much repair it needed.
What changed because we spent those tokens?
Exploring an unresolved product question may require several candidate solutions. Agree what the experiment should teach you, compare the results, and retain the reasons for your choice. Factory distinguishes that exploration from correcting violations of agreed requirements, drawing on Toyota and CynefinA framework for matching an approach to a situation: ordered situations have cause and effect that are clear or discoverable through analysis; complex situations need exploration; chaotic situations need action to establish stability.One product can contain precise coding rules and unresolved questions about what users need..
Research has examined solution quality alongside speed. In an experiment at Procter & Gamble, Dell’Acqua, Mollick et al. (2025) studied 776 professionals working on product problems. Individuals using AI matched the solution quality of two-person teams without it. The study measured solution quality as well as time spent; the AI groups also completed the work faster. Applying that finding to your work requires a useful way to assess quality.
Evaluate the result and the criteria
Clear criteria help an agent evaluate and revise its work between human decisions. Tests compare behavior with defined expectations. RubricA guide that names the qualities to assess and describes what meeting each criterion looks like.For a dashboard, it might require the reason for each case’s priority to be visible and supported by the case details. describe qualities a reviewer should assess, while GoldenAn accepted result retained as a reference for assessing later results.An approved support reply shows the tone and level of detail expected in later replies. examples show accepted results. A Judge/EvaluatorAn AI used to assess work against defined criteria. Check its judgments against examples evaluated by people who understand the task.For a dashboard, it can assess whether the explanation of each case’s priority is supported by the case details. or human reviewer can investigate questions the existing checks leave open. Evidence from product use can reveal where the criteria themselves need to change.
Check the criteria against examples people have assessed, including CounterexampleA plausible but unsuitable result retained with the reason it fails the relevant criteria. It helps assess later results and the reviewer itself.A polished dashboard that hides a case the agreed rule marks as urgent shows what the reviewer should reject. that look plausible but fail an important requirement. A grader can reward the wrong properties. If it accepts a dashboard because the layout looks polished while urgent cases remain hard to find, the agent may keep improving the layout without addressing that problem.
Preserve feedback and evaluate its effect
Retained feedbackUseful feedback carried forward into a plan, test, decision record, or guidance for later work.Keep the reason for a rejected option and the conditions that would justify reconsidering it. preserves something useful for later work: a corrected instruction, a test case, or the reasons behind a decision. Record why a variant was rejected and what might justify reconsidering it. To establish that the system improved, examine whether the resulting change helps on later comparable tasks. The Factory chapter describes that evaluation.
Evaluate the model and its surrounding setup
Comparisons with a fixed model show how much the surrounding setup can affect results. LangChain reported an increase from 52.8% to 66.5% on Terminal-Bench 2.0 while keeping GPT-5.2-Codex fixed. Its HarnessThe software around a model that lets it act, inspect results, and continue working: its execution loop, tools, context management, and controls. Harness engineering also covers checks and review arrangements across technical systems.An agent that can read files, run checks, and correct its work uses a harness. changes included verification, context delivery, and time management.
Such results give teams a reason to evaluate context and execution mechanisms alongside model choice. To choose an investment, compare the available combinations on tasks that matter to your team, including quality, review effort, and total cost. Harness develops the technical work behind that comparison.
Keep the work useful and reviewable
Sprawl occurs when generated work exceeds what the team can use or review. SlopPlausible, generic work that misses what makes it fit a particular product or task. It can ignore local coding conventions, architectural decisions, or brand requirements.A dashboard invents visual styles despite an existing set of approved components. is plausible, generic work that misses the requirements of a particular product. Either can consume the time saved during implementation.
Bound the task, agree who will inspect the result, and give that person enough time and evidence to do so. Before asking for more variants, decide what you need to learn from them.
A generic result may reveal missing product context, weak checks, or a review that rewards the wrong properties. Give the agent the relevant decisions and examples, then use tests and review to find where the result still misses the requirements. Quick, inexpensive feedback supplies BackpressureQuick, inexpensive feedback from checks built into the agent’s workflow. As the agent works, these checks report problems it can correct immediately.When the agent tries to save a code change as a commit, an automatic check rejects a variable name that breaks the project’s naming rules. The agent corrects the name. Its next commit attempt triggers the check again. during implementation. Review gates assess questions that need more time and judgment. Give reviewers that product context too. Factory shows how to evaluate improvements across comparable tasks.
I closed the original talk that gave birth to this book with a line I still believe:
Build things that would not exist otherwise.
For your next task, which product decisions and examples would help the agent produce something useful to your users?